
India's AI, built from the ground up
BharatGen is an AI company. We build the data, the research and open-weight AI models for text, speech and vision, so anyone can build on them.
Built from scratch. Open weights. Made for India.
Four families of open‑weight AI models
Each one pretrained by our own team, on Indian data.
Param
22 Indian languages and English, with reasoning, code, maths and tool use.
Text models →Speech-to-textShrutam
Speech-to-text in 12 Indian languages, even when speakers switch mid-sentence.
Speech models →Vision · VLMPatram
Vision language models that read forms, tables, charts, stamps and photographs.
Vision models →Text-to-speechSooktam
Natural text-to-speech with voice cloning, in 11 Indian languages and English.
Speech models →Real outputs from our models
Nothing here is staged or edited. Pick a model to see what it can do.
Write a binary search program in Python. All comments in the code must be written in Telugu language.
Code · TeluguSee how it reasoned
User binary search కోసం Python program కోరారు. Comments అన్ని Telugu లో ఉండాలి. Binary search సాధారణ algorithm, array, low, high, mid. Telugu లో వివరణలు ఇవ్వాలి. Code లో comments Telugu లో ఉండాలి, code logic correct ఉండాలి. Python లో function name in English, comments Telugu.
def binary_search(arr, target):
    # ఈ ఫంక్షన్ లక్ష్య విలువను కనుగుకోవడానికి binary search ను అమలు చేస్తుంది
    low = 0
    high = len(arr) - 1

    while low <= high:
        mid = (low + high) // 2

        # మధ్య విలువను పరిశీలిస్తాము
        if arr[mid] == target:
            # లక్ష్య విలువను కనుగొన్నాం, దాని index ను తిరిగి ఇస్తాం
            return mid
        elif arr[mid] < target:
            # లక్ష్య విలువ పెద్దది, కాబట్టి low ను పెంచుతాం
            low = mid + 1
        else:
            # target చిన్నది, కాబట్టి high ను తగ్గిస్తాం
            high = mid - 1

    # లక్ష్య విలువ లేదు, -1 ను తిరిగి ఇస్తాం
    return -1

# ఉదాహరణ వినియోగం
arr = [2, 3, 5, 7, 11, 13]
target = 7
result = binary_search(arr, target)
print(f"లక్ష్య విలువ {target} యొక్క index: {result}")
Real output, not edited. Source: Param2 model card ↗ · More from Param2 →
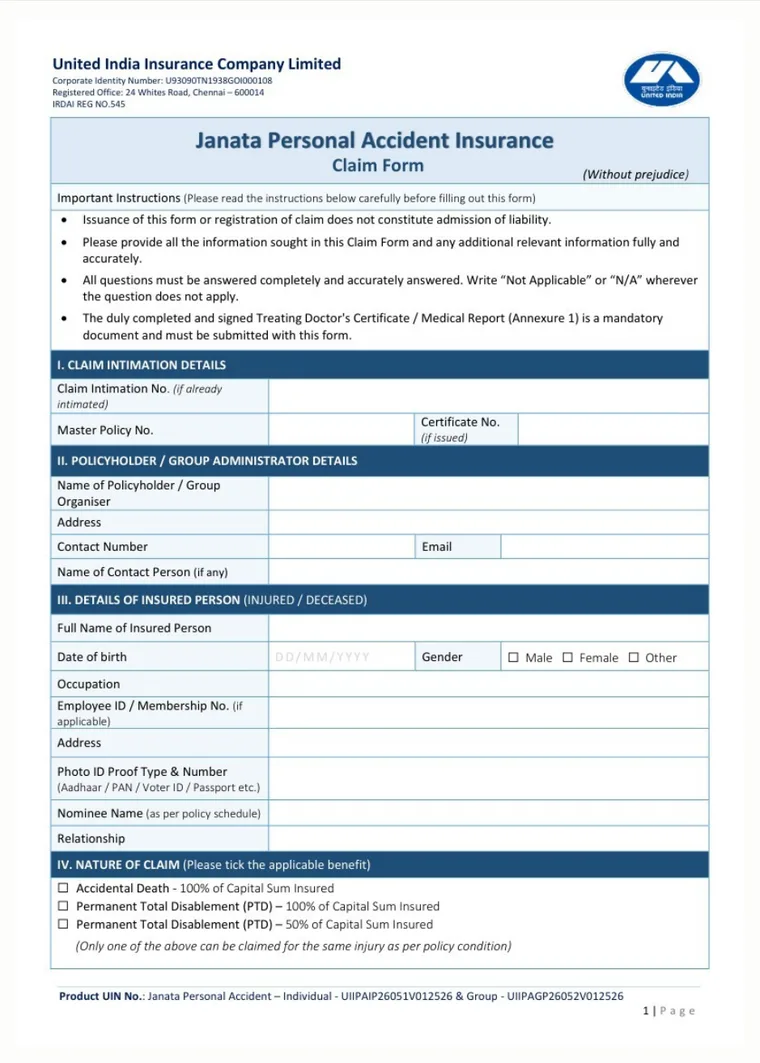
"Tell me how to fill it, what all fields are necessary and how many max claims can i make?"
Thinking step by step:
- The document contains a section titled 'Important Instructions' which outlines the procedure for filling the form.
- The instructions state that the form must be filled out completely and accurately, with 'Not Applicable' or 'N/A' written where questions do not apply.
- The instructions also specify that the treating doctor's certificate or medical report (Annexure 1) must be submitted.
- The form includes a section 'IV. NATURE OF CLAIM' with checkboxes for different types of claims, and a note stating that only one of the listed benefits can be claimed for the same injury.
- The form requires details in sections I through IV, including claim intimation, policyholder details, insured person details, and nature of claim.
Fill out the form completely and accurately, write 'Not Applicable' or 'N/A' where questions do not apply, submit the treating doctor's certificate or medical report (Annexure 1), and select only one nature of claim from the options provided.
Real output, not edited. Source: Patram 1.2 model card ↗ · More from Patram →
Recorded with background noise on our Shrutam demo.
திட்டத்திற்கு விண்வெளி அனுபவம் பெறுவதற்காக இந்திய விண்வெளி வீரர் சுபான்து சுக்லா சர்வதேச விண்வெளி நிலையத்திற்கு அனுப்பி வைக்கப்பட்டார். கடந்த மாதம் இருவத்தைந்தாம் தேதி
In English: Indian astronaut Shubhanshu Shukla was sent to the International Space Station to gain space experience for the mission. On the twenty-fifth of last month
Real output, not edited. Recorded on our Shrutam 2 demo. Shrutam 2 on Hugging Face ↗ · More from Shrutam →
Sooktam 2 reading the same railway announcement in four languages: "Hello! Your train will arrive on platform number two in ten minutes."
नमस्ते! आपकी ट्रेन दस मिनट में प्लेटफ़ॉर्म नंबर दो पर आएगी।
வணக்கம்! உங்கள் ரயில் பத்து நிமிடங்களில் இரண்டாவது நடைமேடைக்கு வரும்.
নমস্কার! আপনার ট্রেন দশ মিনিটের মধ্যে দুই নম্বর প্ল্যাটফর্মে আসবে।
नमस्कार! तुमची गाडी दहा मिनिटांत फलाट क्रमांक दोनवर येईल.
Generated with Sooktam 2, unedited. Get Sooktam 2 on Hugging Face ↗
Made in India, open to everyone
Our own data, our own tokenisers, our own training. Then we publish the weights.
Not fine‑tuned from someone else's model
Pretrained by our team on a corpus we curate with provenance, so we know what each model learned.
Download, run and adapt
On Hugging Face and AIKosh, to run on your own machines and fine-tune for your work.
Languages, culture and context
Code-mixed sentences, Indian names, government forms and regional scripts.
Benchmarks built for India
BhashaBench and ParamBench, open to anyone testing models on Indian knowledge.
From hospitals to newsrooms to state governments
Organisations building on our models.

Amrita Hospitals
Built MedSum, which transcribes consultations and drafts clinical notes, on BharatGen's open-weight AI models.Read the case study →
India Today Group
Unveiled Sutra, an AI news anchor built with BharatGen's AI models, at the India AI Impact Summit.Read the case study →
Government of Andhra Pradesh
Partnering with BharatGen on a Telugu-first AI tech hub for citizen services.Read the news ↗Build with BharatGen
Developers, enterprises, government teams and researchers can start with our open weights today.